EU sovereign AI inference
Your AI, running in Europe. Faster than you are used to.
Fast AI inference that you keep control of: open-weight models on purpose-built hardware we own and run in Munich. One OpenAI-compatible API, from your first API key to your own racks.
Agents that don’t make you wait.
Answers before the pause gets awkward.
Your appointment is moved to Tuesday, 10:30. Anything else I can do for you?
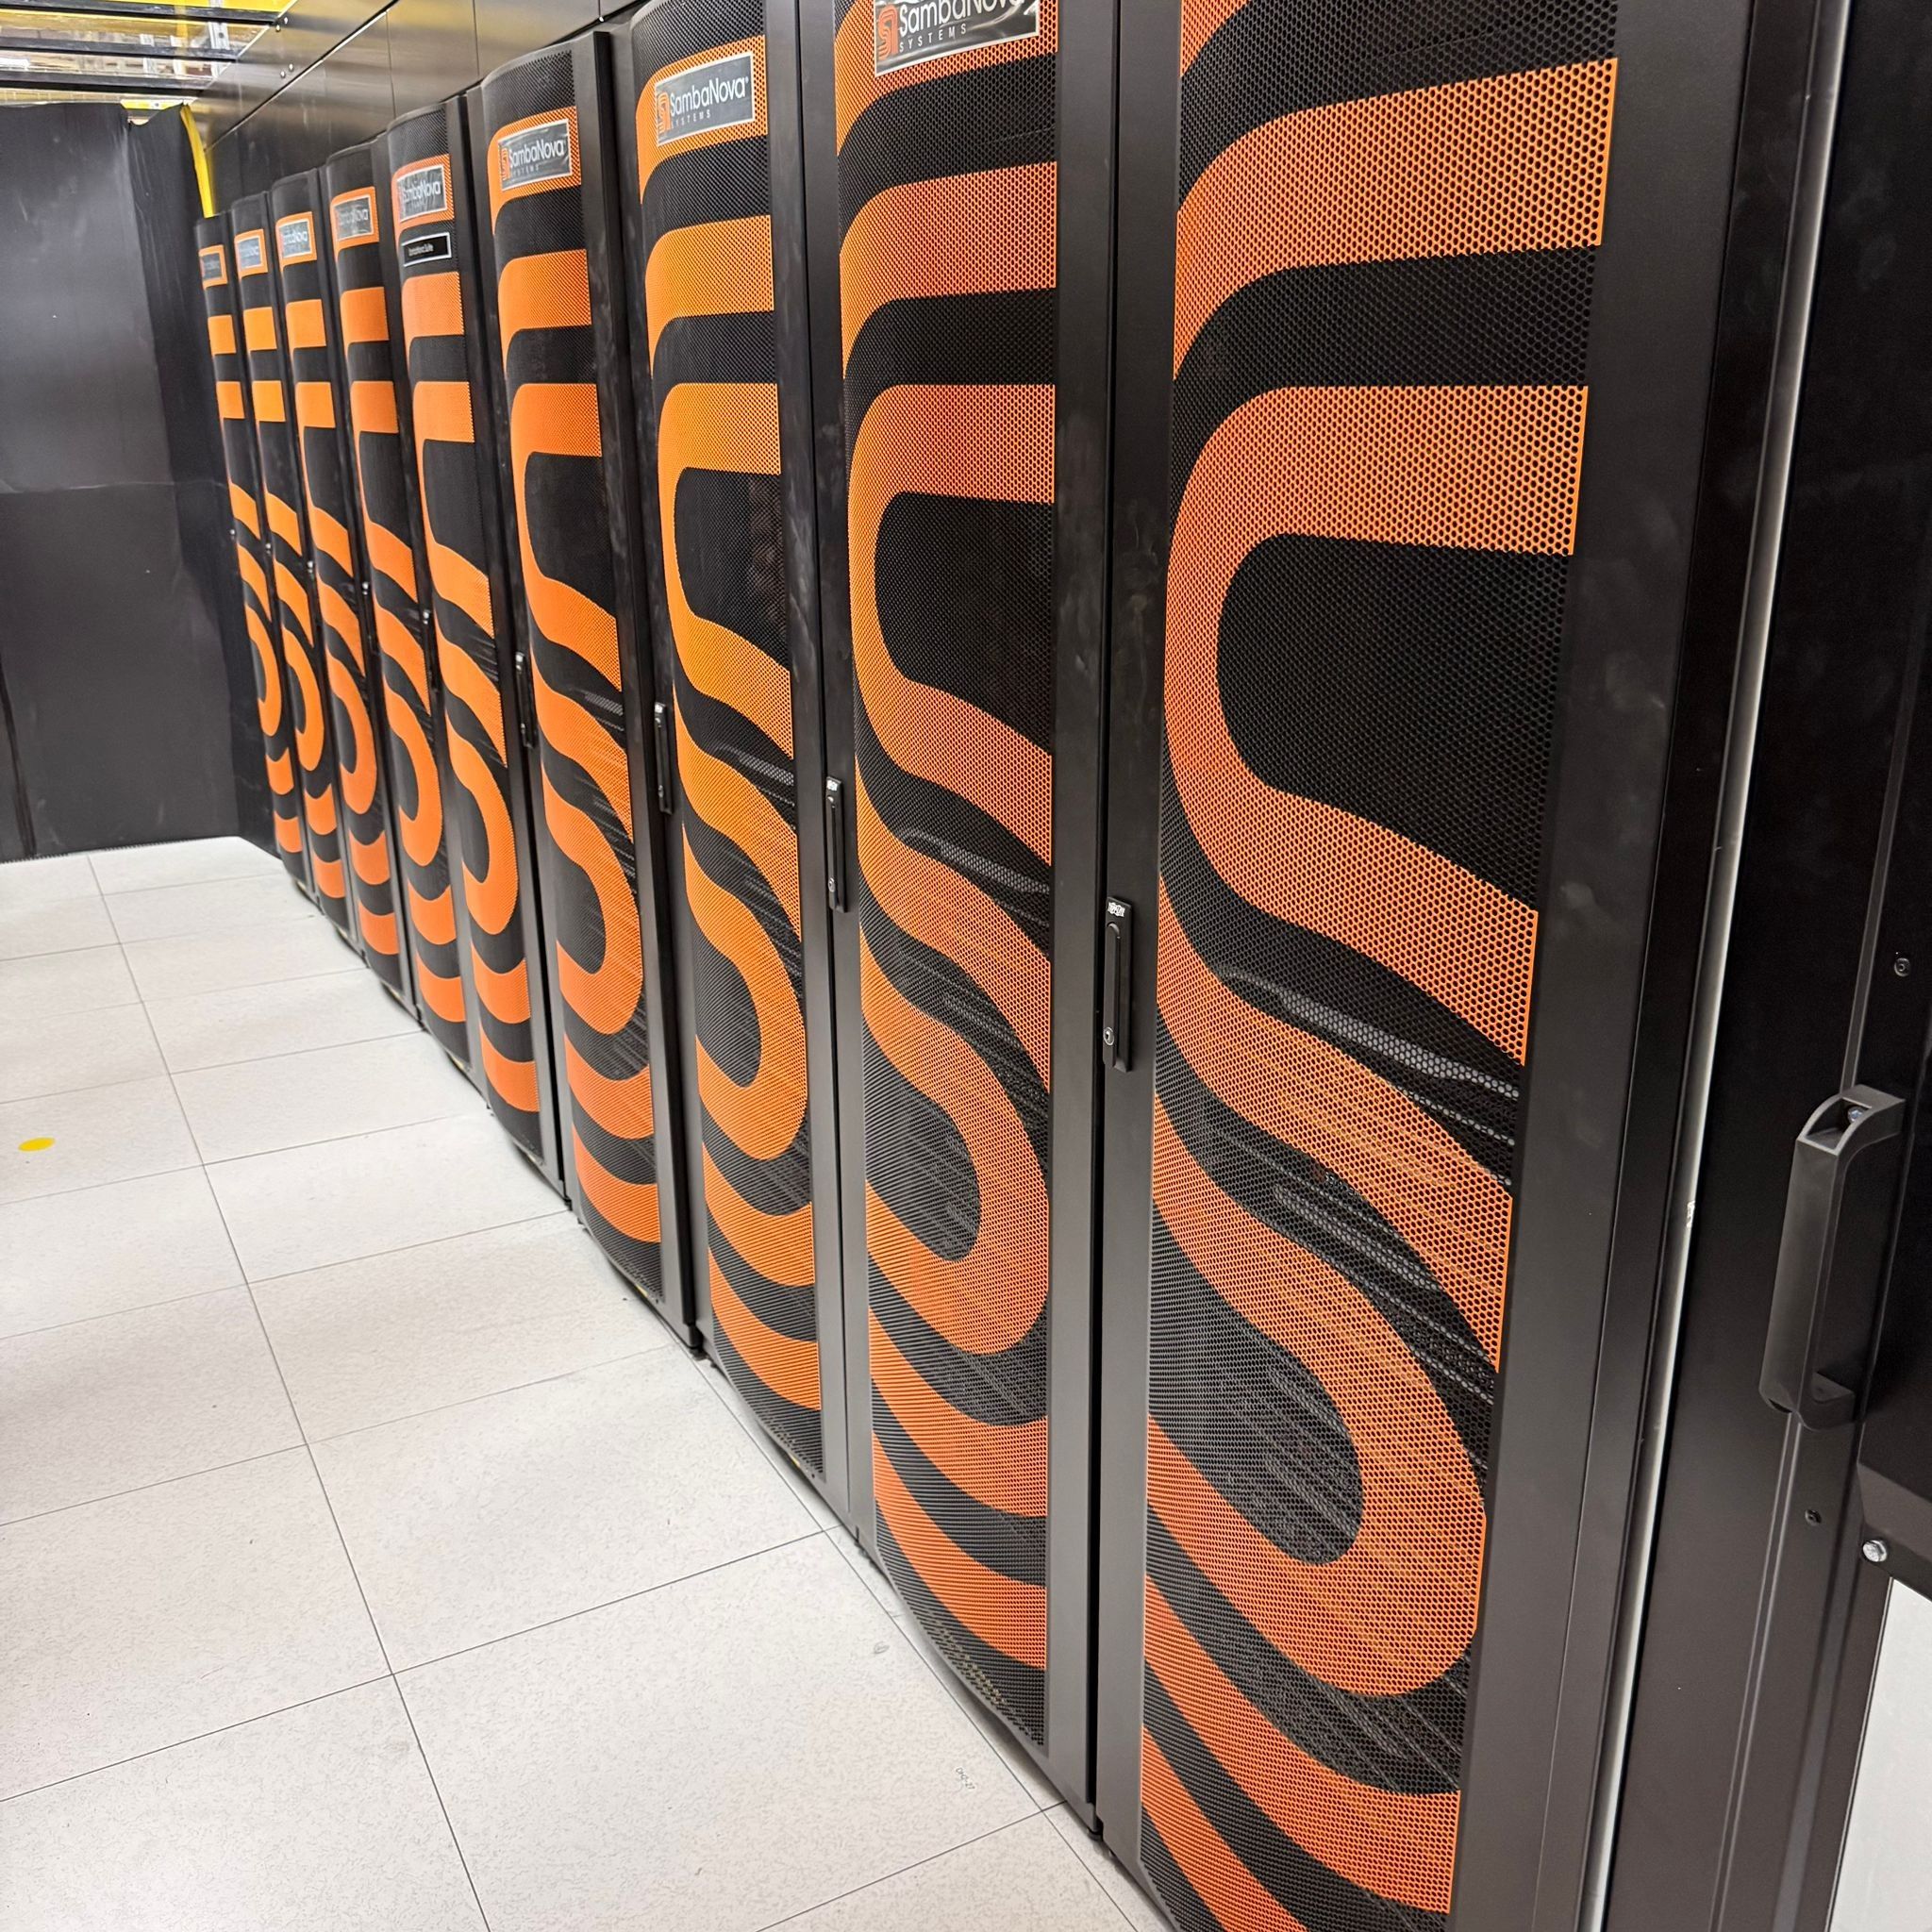
Your data stays in Europe.
- EU sovereign models
- Zero Data Retention Policy
- ISO 27001 certified
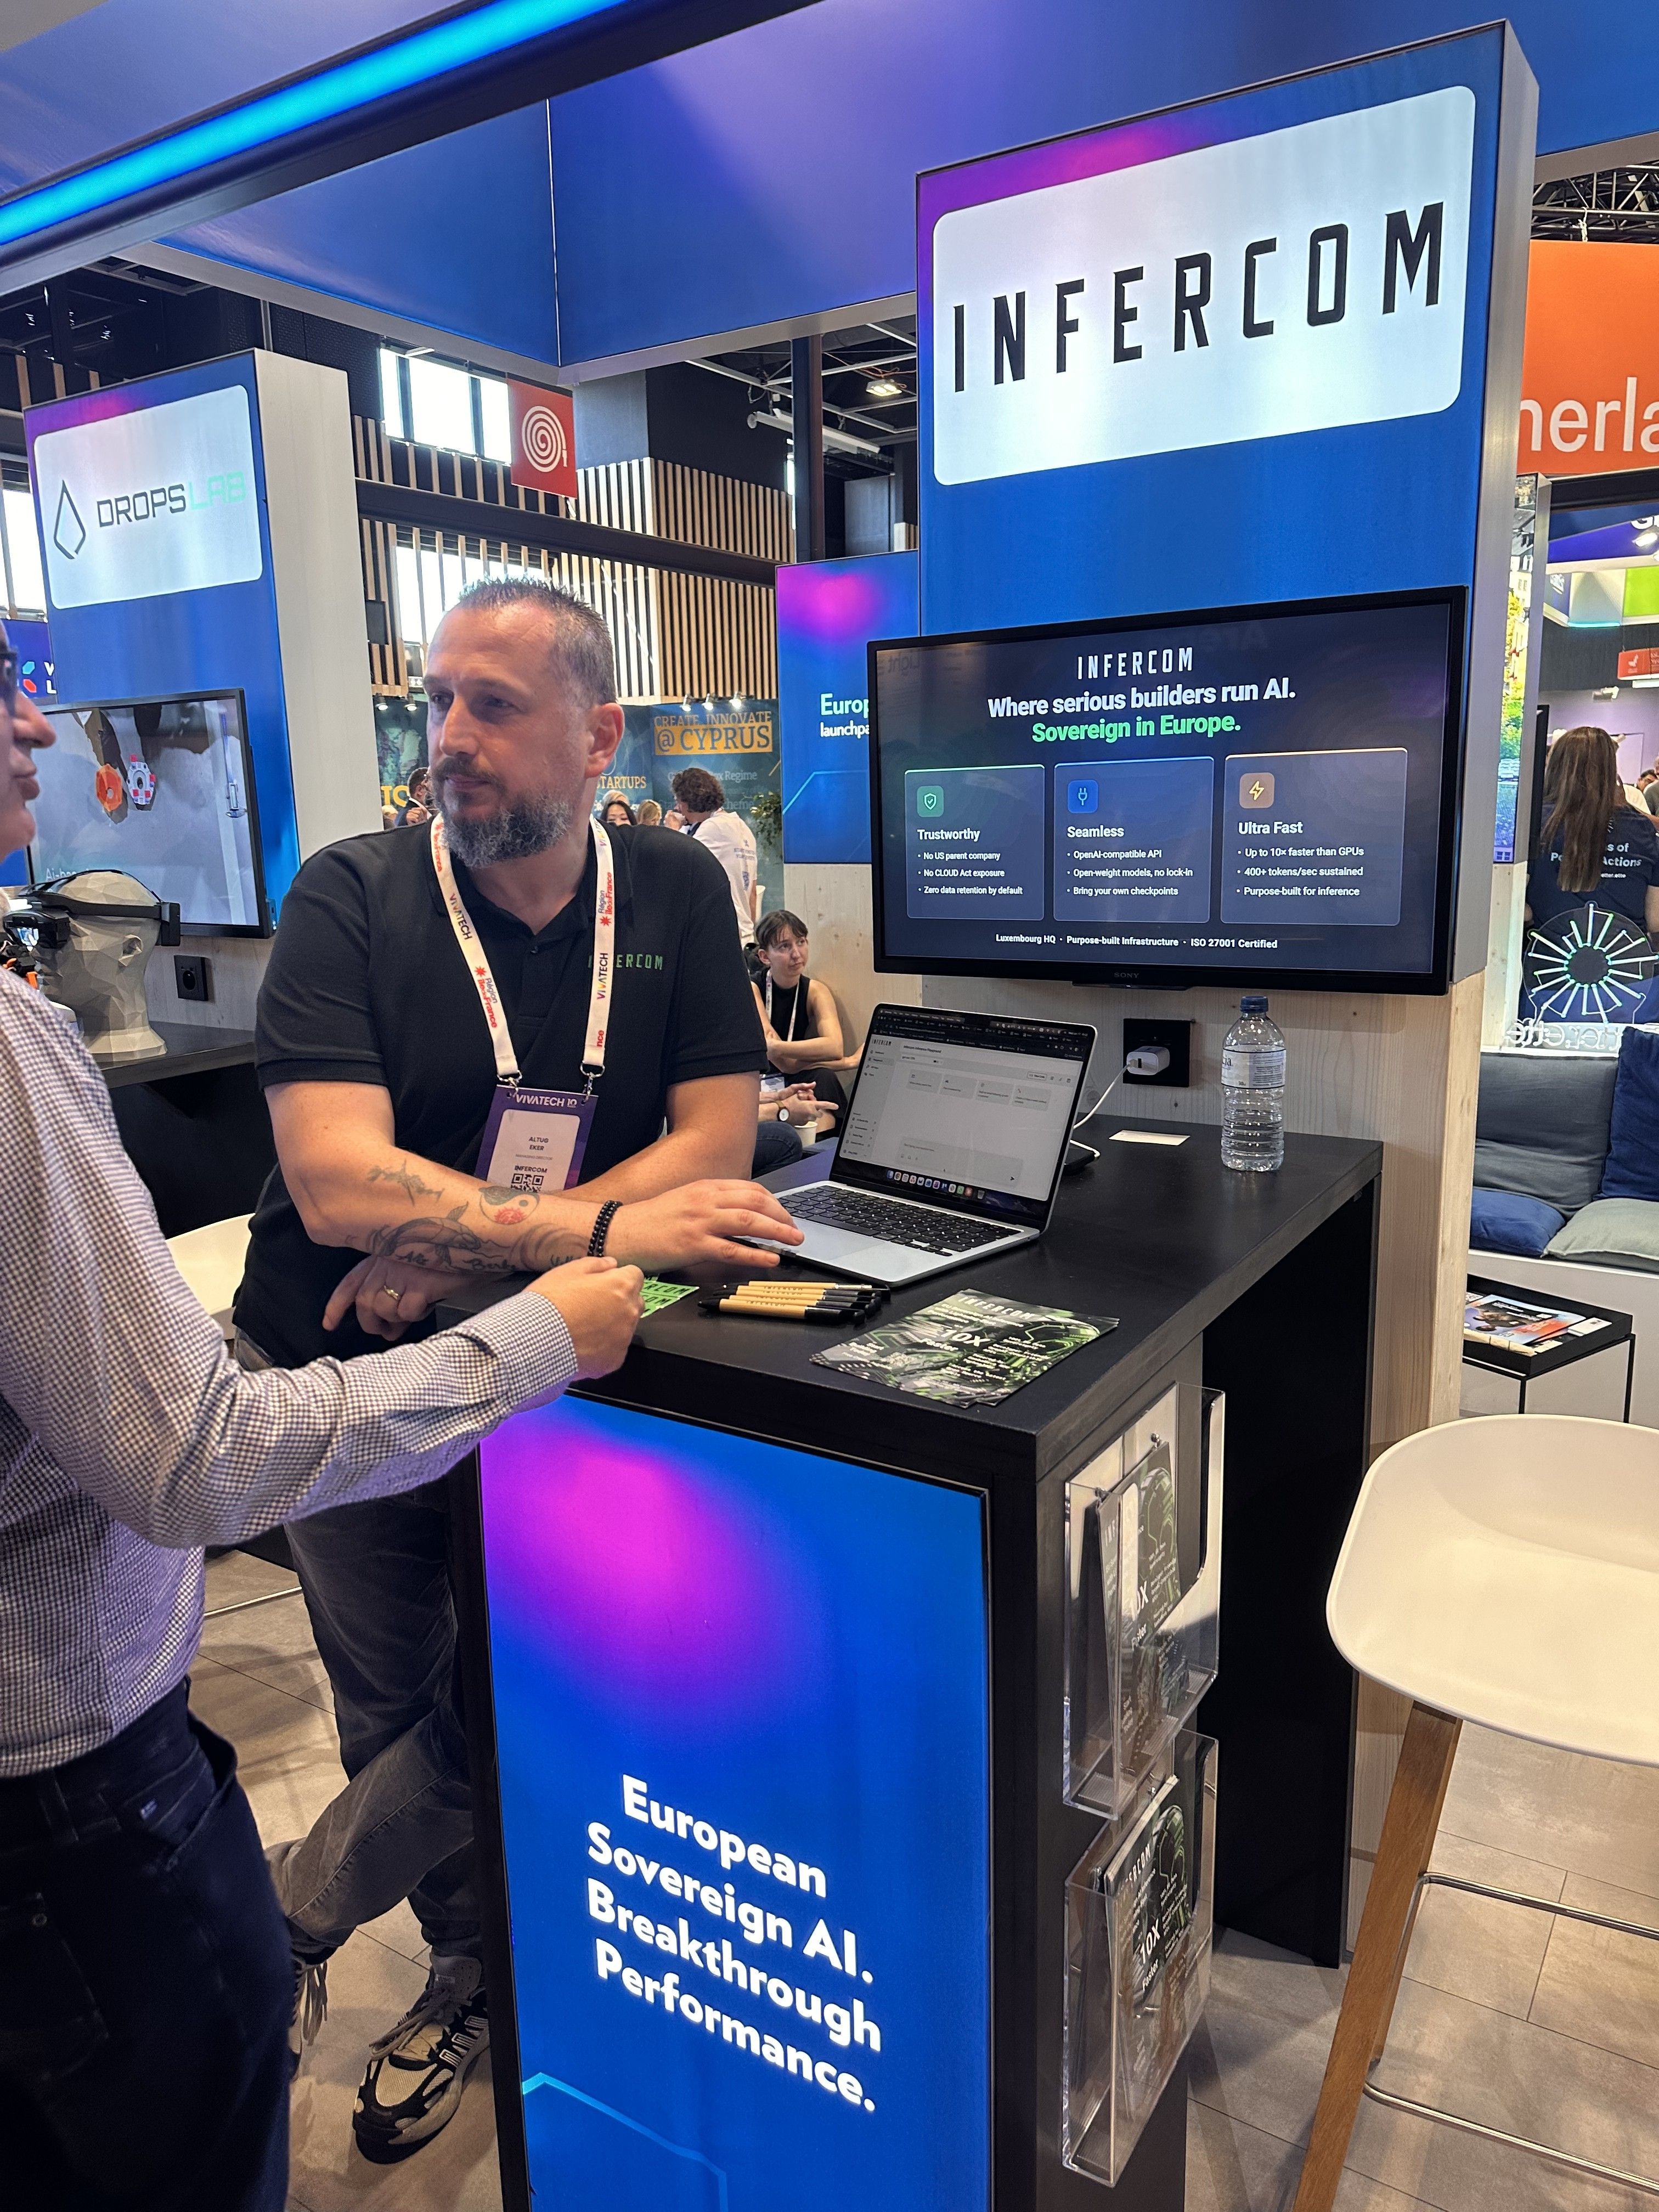
People you can reach.
- Luxembourg company, no US parent
- A team you talk to directly
- From your first key to your own racks
Output Throughput, p50, 10K input / 1K output, single request. Last measured: July 2026.
Why it matters
Two things break AI products
Someone else decides
Your data, your models and your service depend on a provider. When its law, its owner or its catalog changes, your product changes with it.
Slow answers
Voice agents pause, coding agents stall, users leave. For many products, speed is not a detail. It is the product.
What we do
Open-weight models on hardware we own
We run open-weight models on hardware we bought and operate ourselves, in a data center in Munich. Inference only: we do not train models, and prompts and outputs are never written to disk.
- Luxembourg company, controlled in Europe, no US parent
- EU sovereign models processed in Munich
- Every dependency named, including what is not European yet
Why it is fast
Built for inference, not repurposed
Purpose-built AI chips keep the model's working data next to the compute, so data does not travel back and forth as it does on GPUs. The result is up to 10x faster inference than GPU-based alternatives, measured on our production API with the method published.
Models
Models that run in Munich
Current open-weight models, served at the precision their makers released them in.
Try it
Switch in one line
Point your OpenAI SDK at our endpoint and pick a model. Nothing else in your code changes.
from openai import OpenAI

client = OpenAI(
    base_url="https://api.infercom.ai/v1",  # the one line that changes
    api_key="your-api-key",
)

response = client.chat.completions.create(
    model="MiniMax-M2.7",
    messages=[{"role": "user", "content": "Hello from Munich"}],
)
Grow without switching
Same API, from your first key to your own racks
Only the operating model and the location change. Your code and the performance stay the same.
Who builds on it
European routers, platforms and solutions run on Infercom





That device is limited and we need infrastructure, and private infrastructure. That's why we are working with Infercom, to actually run bigger models with lower latency.
 Levent AkyilCEO & CTO, co-mind.ai
Who we are
We carry the infrastructure, you build the product
We choose and architect the infrastructure that fits each job, and run it for you. Today that is SambaNova's chips, built for fast inference. A small European team you can reach directly, with a roadmap you can influence.